The Technology Behind Our AI Inference Products
Semidynamics develops the processor, acceleration and memory technology at the heart of its AI inference products, from accelerator chip to rack
Our All-In-One RISC-V architecture unifies CPU, vector (RVV) and tensor processing in a coherent AI pipeline. The units share a single memory space and instruction stream, compiled with standard LLVM and GCC tools. Paired with Gazzillion Misses™, our latency-hiding memory technology, this architecture keeps data flowing to the compute engines
The result: seamless integration, superior efficiency, and system-level reliability for demanding AI inference workloads

Technology blocks
All-In-One Architecture
Brings CPU, vector and tensor processing together under a single instruction set, shared memory space and instruction stream. Standard LLVM and GCC tools support the balance of programmable processing and AI acceleration within our chips.
RISC-V Processing
Programmable CPU technology provides the foundation for our AI chips, combining Linux support with control and general-purpose processing alongside AI acceleration.
Vector Unit
Slices, packs, and polishes tensors to keep the pipes full.
Tensor Unit
Chews through big tiles of matrices and tensors at blistering throughput.
Gazzillion Misses™
Soaks up memory stalls, keeping hundreds of outstanding memory reads in flight per core to sustain high compute utilisation with high-capacity memory, so compute never waits. This capability requires no changes to application code.
High-capacity Memory for Large Models
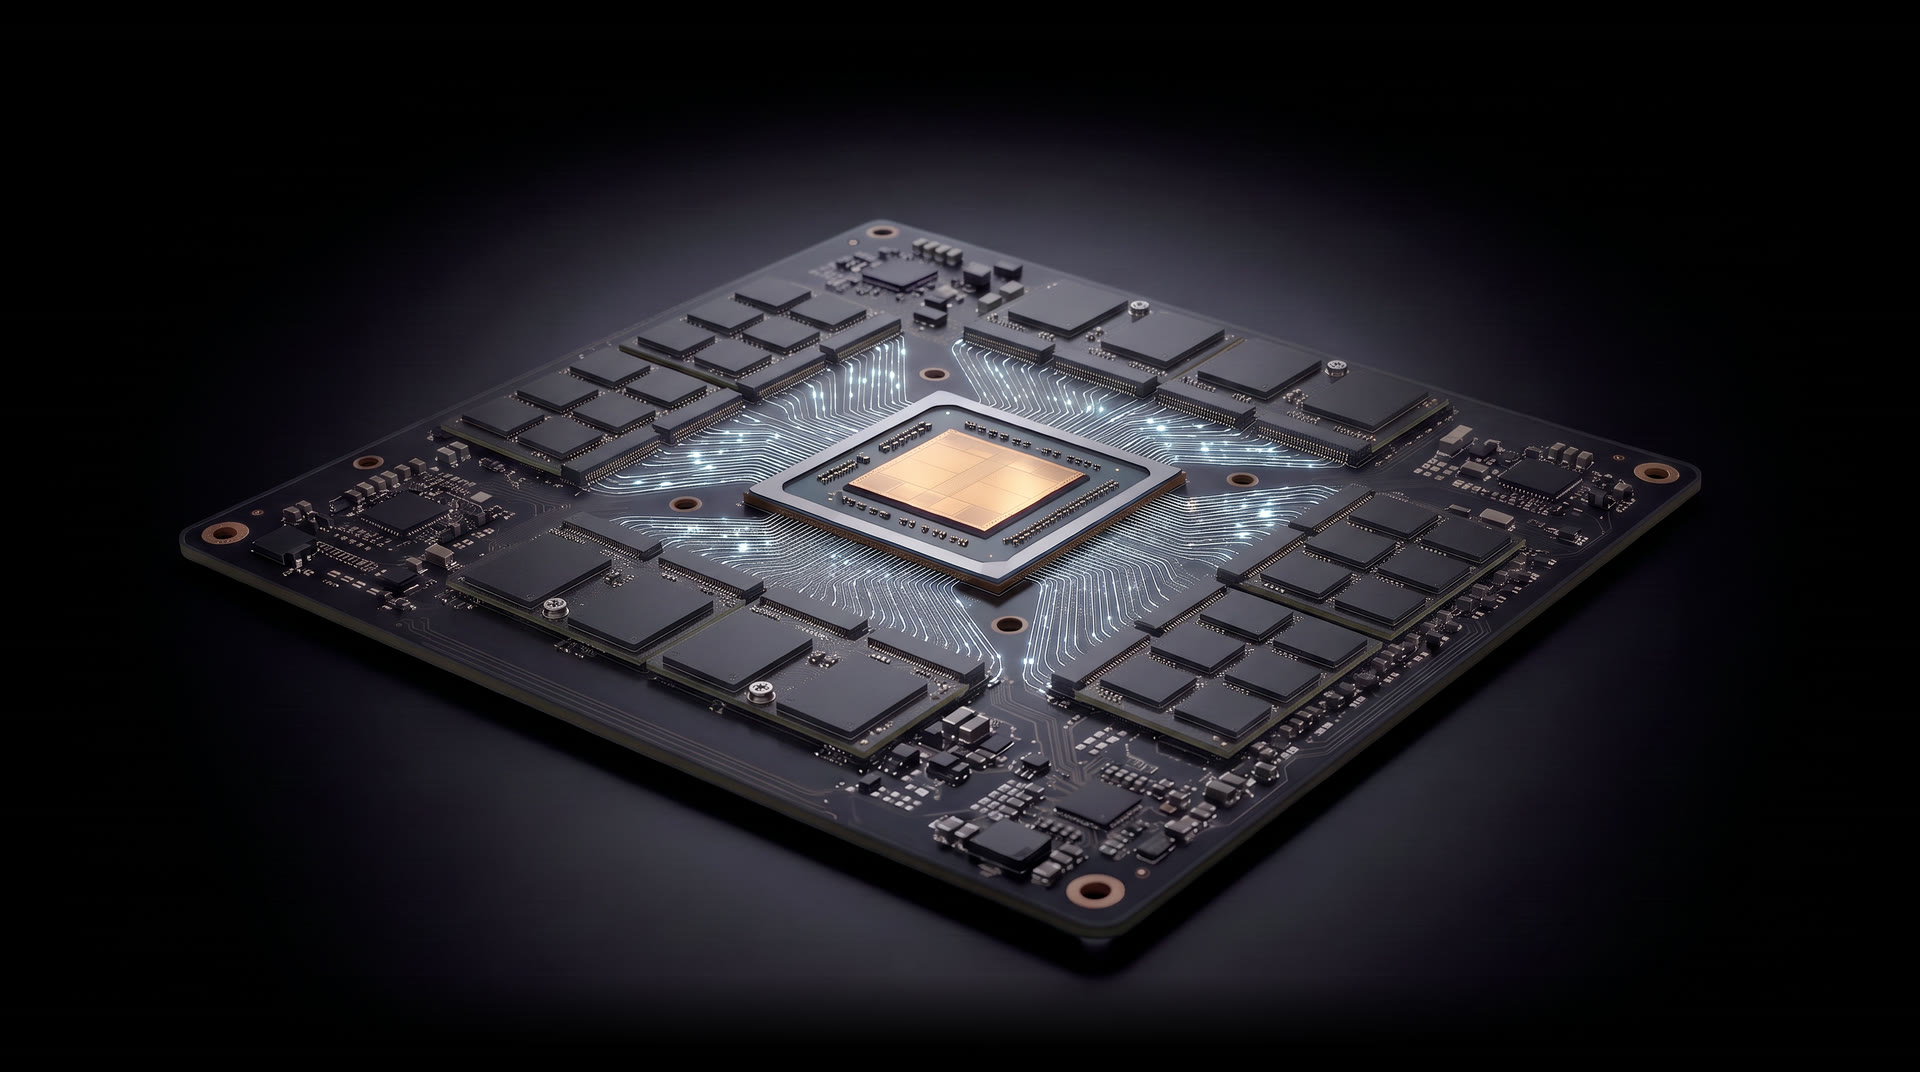
High-capacity LPDDR memory enables terabytes per accelerator chip.
Gazzillion Misses™ helps sustain compute utilisation while accessing this capacity, supporting large models and the KV-cache demands of long-context inference.
Native FP64 for
HPC and Science
Native FP64 hardware supports double-precision HPC and scientific workloads alongside the platform’s AI inference capabilities.
Engineered Together
from Chip to Rack
Our processor and memory architecture provides the foundation for Semidynamics AI inference chips and complete rack systems. Hardware and software work together to support demanding models and efficient inference at scale.