The Architecture for the Next Generation of AI
The era of thrashing data between memory and processors is over.

Semidynamics brings compute, memory and interconnect together in a unified hardware architecture engineered to master the world’s largest AI or agentic AI models. From the chip to the rack, the architecture is designed around keeping data available to the compute that needs it.
We don’t just reduce latency—we eliminate the bottlenecks that hold back modern AI.
From Silicon to
Complete Systems
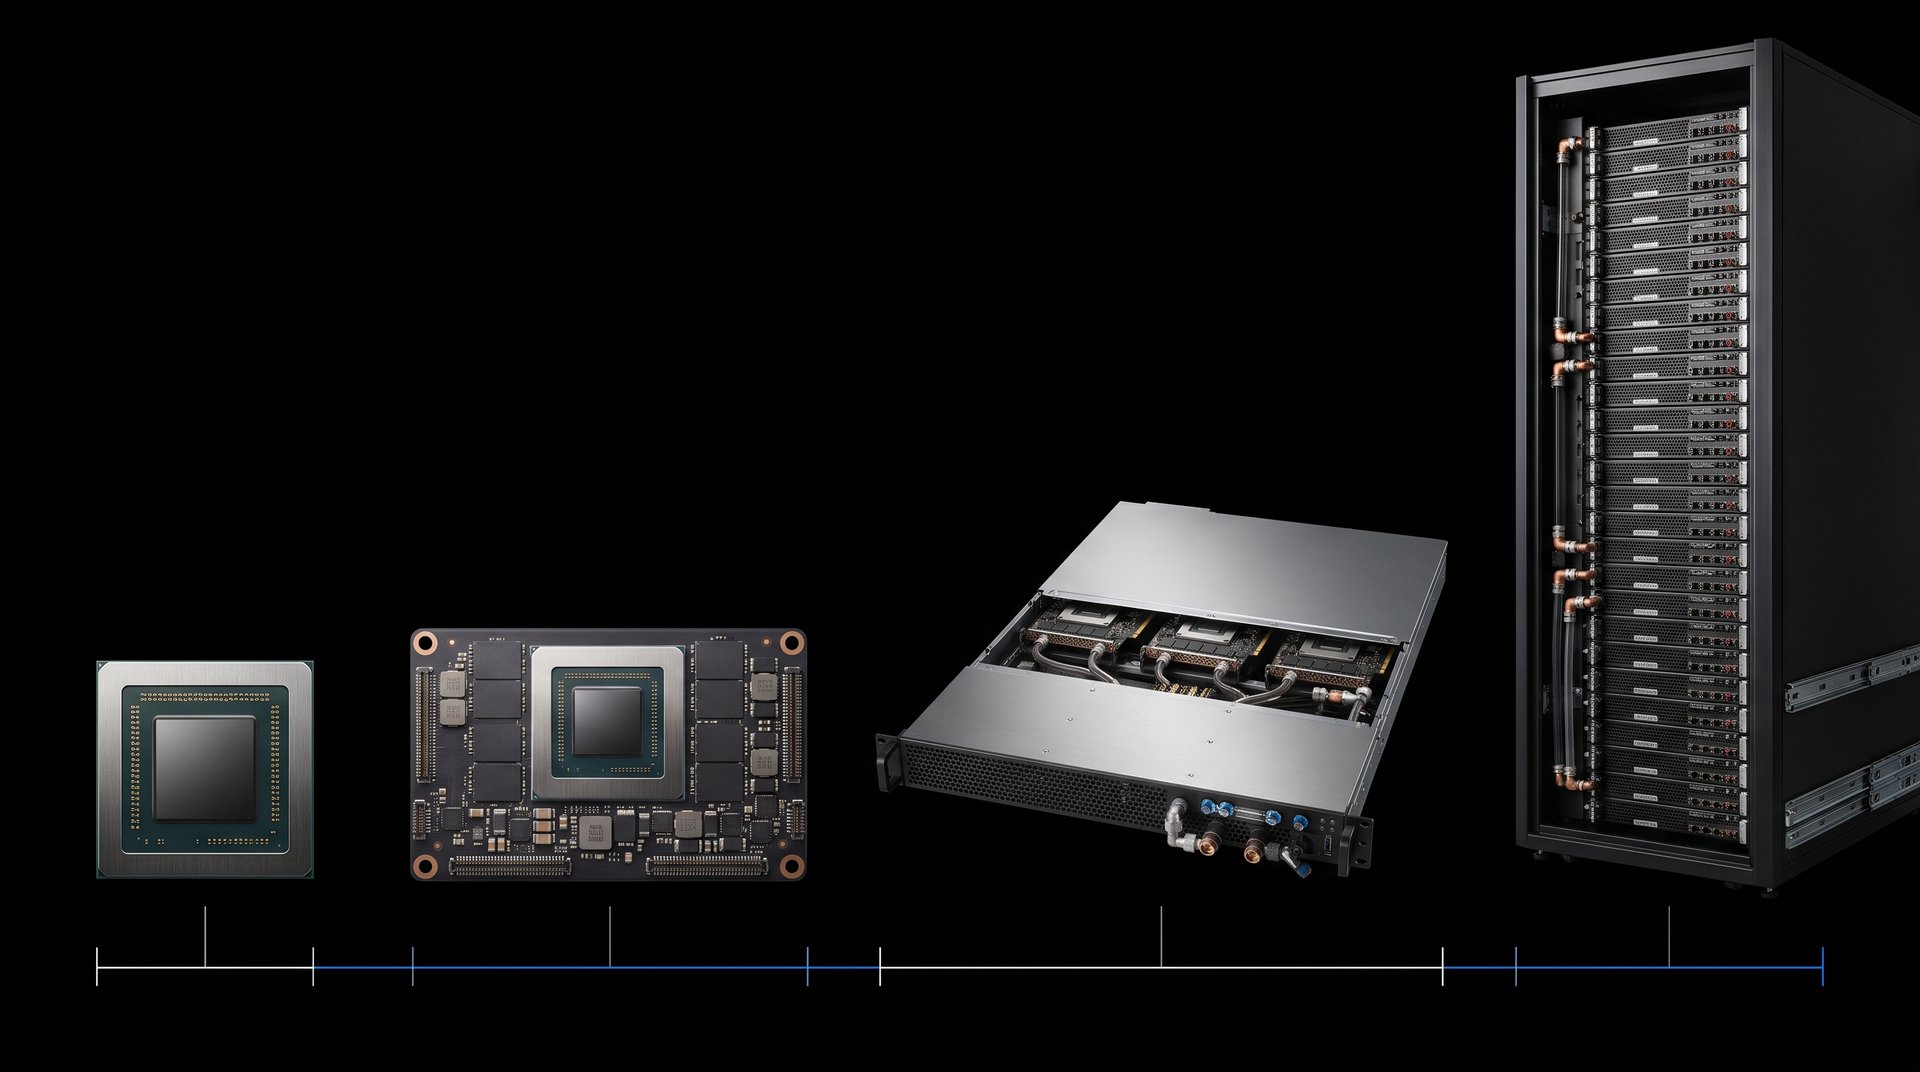
Our AI inference chips combine RISC-V processing with vector and tensor acceleration and our memory technology.
Board-level systems and complete liquid-cooled racks bring these capabilities together at infrastructure scale, supported by the Semidynamics software stack.
Talk to us about the right product and system configuration for your models and deployment requirements.
Terabytes of Memory Enable Lower Cost per Token
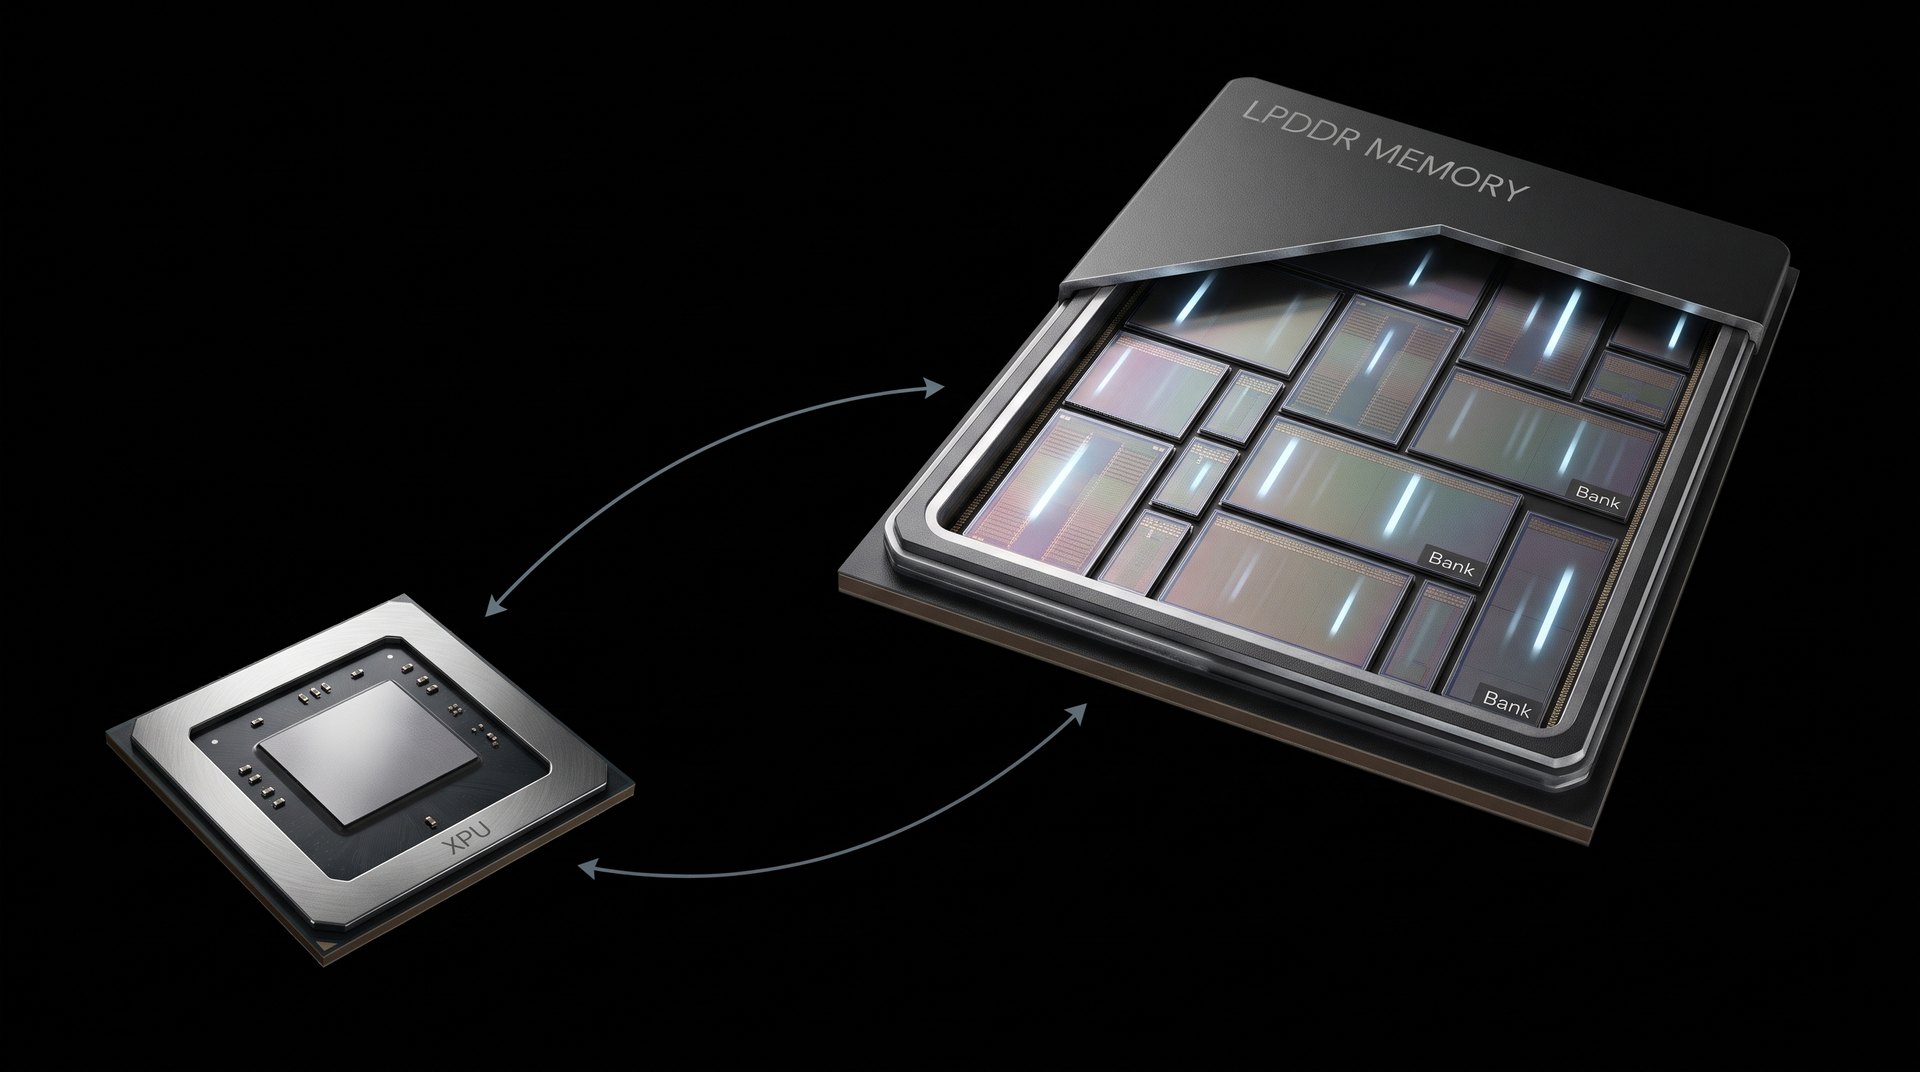
Semidynamics uses high-capacity LPDDR memory instead of HBM to enable terabytes per accelerator chip and multiple times the capacity per node compared with conventional HBM-based systems.
Larger models, longer contexts and growing KV-caches can stay in memory, allowing each rack to serve more users and lower the cost per token.
Infrastructure for Demanding Models
Our products target large-model and long-context LLM inference, Mixture-of-Experts models and autonomous AI agents.
They address the needs of AI service providers, hyperscalers and infrastructure operators, as well as sovereign AI programmes and AI Factories.
Native FP64 support also serves HPC and scientific computing workloads.
Total Programmability
Built on RISC-V and fully compatible with Linux, our hardware empowers developers with deep optimisation capabilities and standard tool support.
Seamless Integration
Full compatibility with your existing AI software stack ensures your models and workflows transition smoothly. Native PyTorch and upstream-compatible vLLM deployment are supported by an integrated Linux environment and driver stack.
Unified Memory
Experience a unified memory view across your entire data centre, simplifying programming and maximising throughput.
Evaluate Semidynamics for Your Workload
Talk to us about your models, context lengths, concurrency and deployment requirements, and the right evaluation route for your project.
Evaluate Semidynamics for
Your Workload
Talk to us about your models, context lengths, concurrency and deployment requirements, and the right evaluation route for your project.