Engineering AI Inference at Every Layer

AI Inference from Chip to Rack

Semidynamics builds memory-centric AI inference systems, from accelerator chip to rack.

Breaks the memory wall Terabytes of memory per node hold larger models and longer contexts, running native PyTorch and vLLM.

Lower cost per token High memory capacity per chip runs large models with less hardware and less energy.

Developed in the EU Engineered with European sovereignty at its core.

Complete AI Inference Rack Solution

Unified Hardware for Large-Scale AI Workflows

Our accelerator chips, board-level systems and liquid-cooled racks bring memory and compute together for large-scale inference.

High-capacity RAM High-capacity LPDDR memory supports larger models and growing KV-caches.

Scale-up Fabric Architecture Extends that capacity across the whole system.

Inference for your largest models

The World’s First Terabyte-Scale AI Inference Unit

Terabytes of memory per accelerator chip provide room for larger models, longer contexts and deep reasoning, with low and predictable latency.

Memory-centric design Uses high-capacity LPDDR memory instead of HBM.

More memory per node Several times what conventional HBM-based systems offer.

Memory economics

More Memory
Lower Cost per Token

More memory per rack means room for larger models, larger KV-caches and longer contexts, so each rack can serve more users. Semidynamics designs its chips and systems around this relationship between memory capacity, inference performance and cost per token.

Powering AI Inference

Large Language Models, Large Context

Keep tokens processing. Our processors and AI engines minimise memory stalls so attention layers and KV-caches stay fed, improving tokens per second and efficiency on modern LLMs. High memory capacity supports large-model and long-context inference, including Mixture-of-Experts models and the growing context requirements of autonomous AI agents.
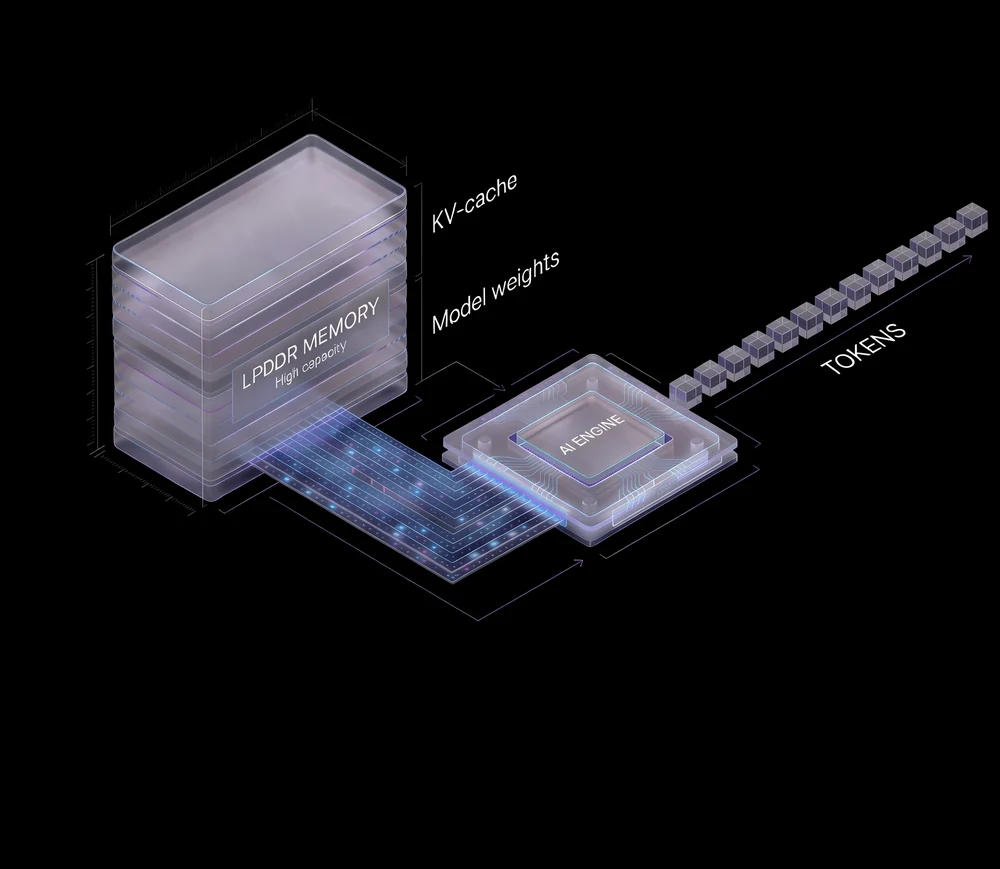
High-capacity LPDDR memory holding model weights and KV-cache feeds the AI engine through many parallel data lanes, producing a continuous stream of tokens

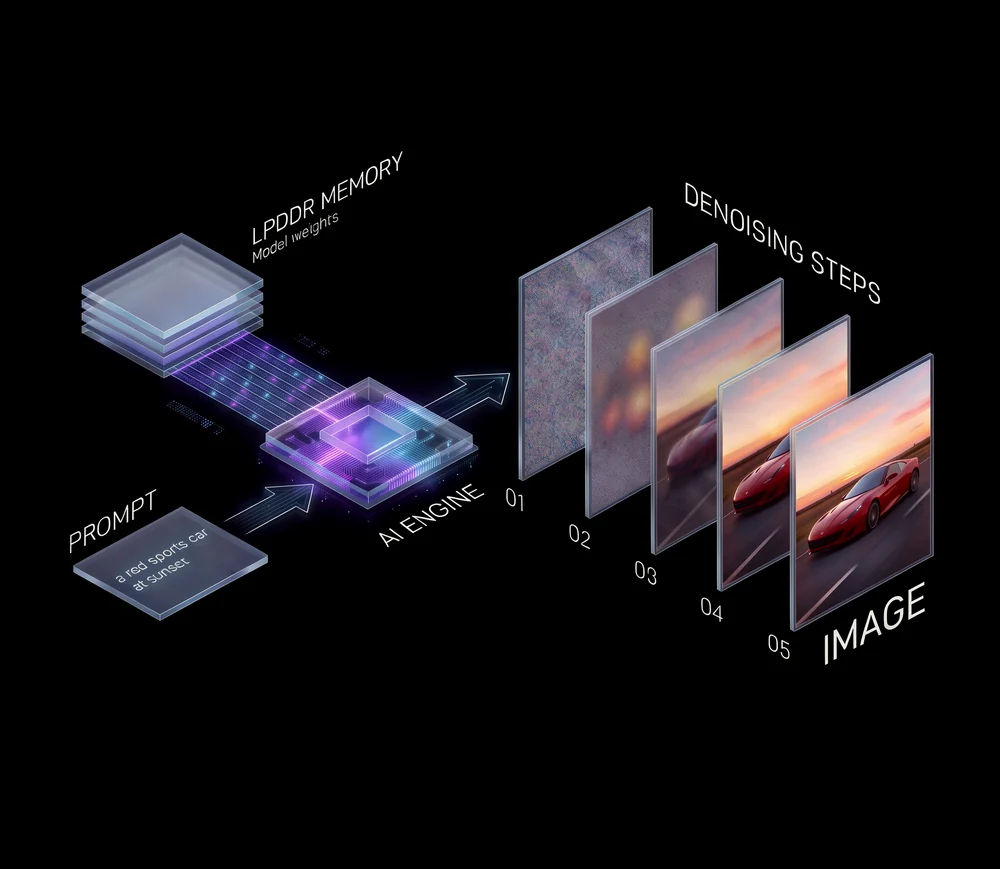
Stable Diffusion & Generative AI

We accelerate the heavy math of generative AI while prioritizing bandwidth. Denoising steps run smoothly and batches scale without choking on memory, giving you an infrastructure that simply evolves with every new model.

A text prompt and model weights from LPDDR memory feed the AI engine, which turns random noise into a clear image over successive denoising steps

Image Classification

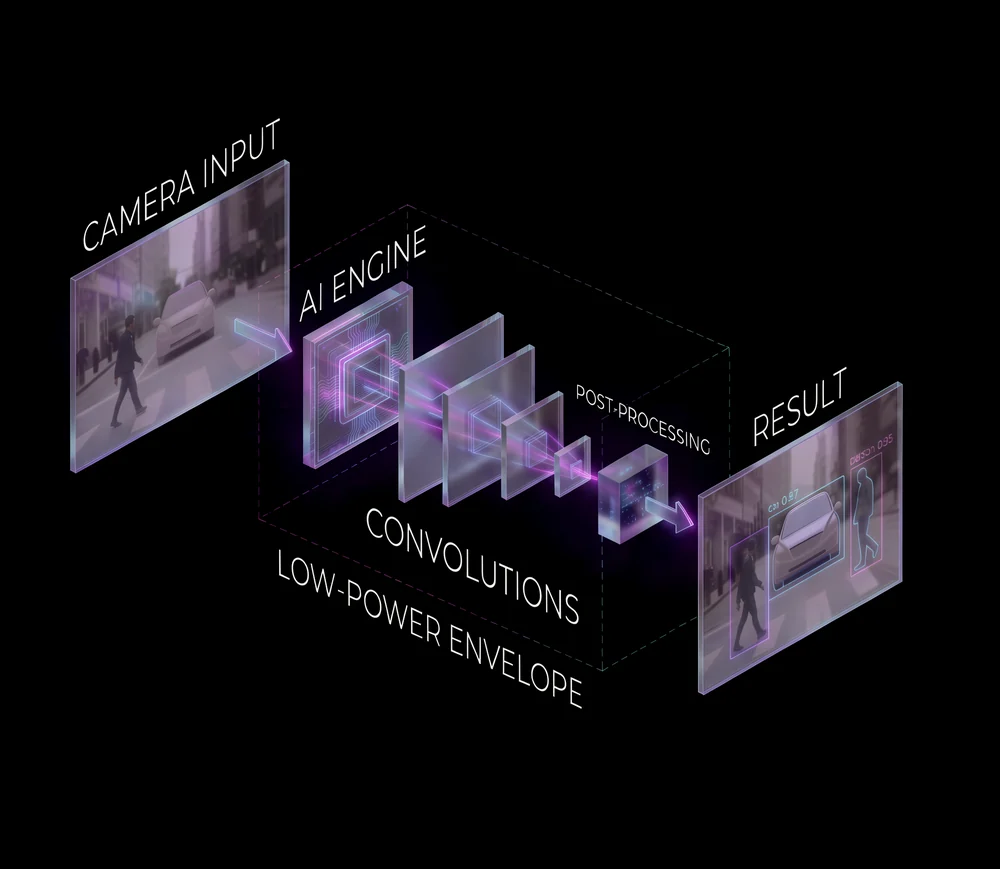
Efficient vector and tensor processing and smart data movement keep convolutions and post-processing responsive, even within tight power envelopes.

A camera frame passes through the AI engine, shrinking convolution layers and post-processing inside a low-power envelope, returning the street scene with the car and pedestrians detected

HPC and Scientific Computing

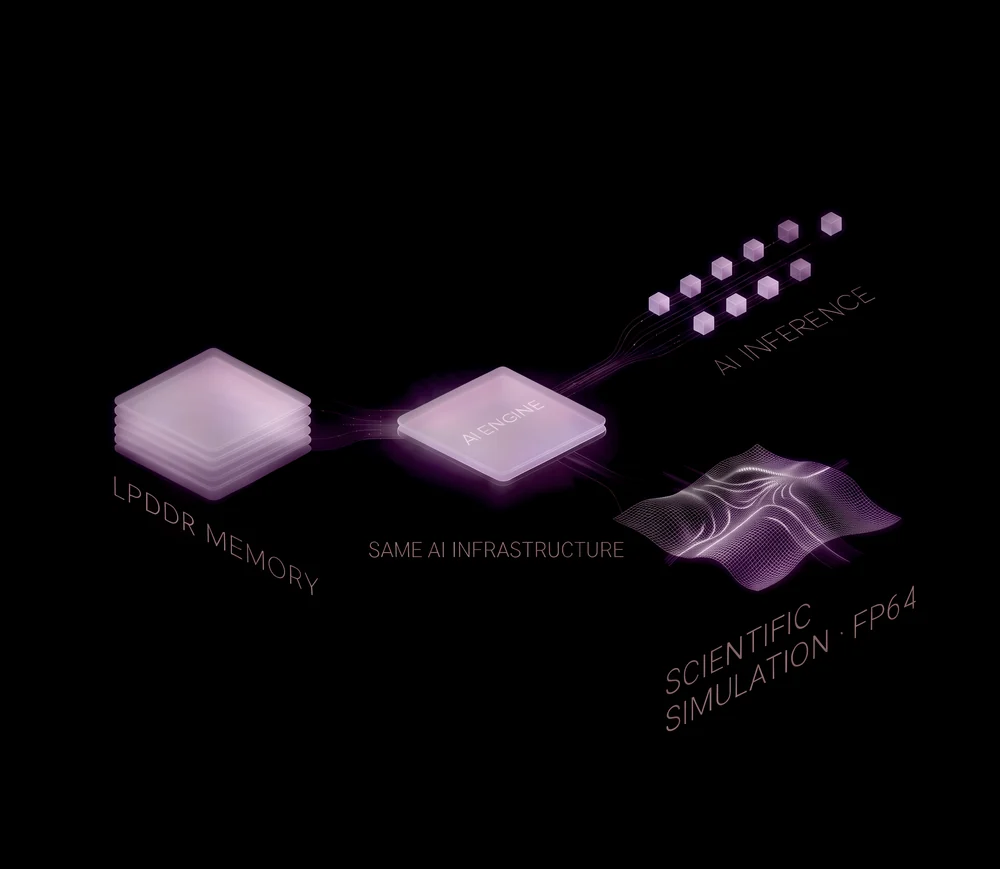
Native FP64 hardware support extends the platform to high-performance computing and scientific workloads that need double-precision processing alongside high-capacity memory.

LPDDR memory feeds the same AI engine that runs AI inference and FP64 scientific simulation
From Semidynamics technology to AI inference products
Deployment audiences

Built for AI Infrastructure

For data centre AI service providers, hyperscalers and infrastructure operators seeking lower cost per token, and European public-sector programmes building sovereign AI capacity.